≥239 tokens/s prompt processing
57.76 tokens/s token generation
hermann@7600x:~/llama.cpp$ ./bench5
ggml_cuda_init: found 5 ROCm devices (Total VRAM: 98224 MiB):
  Device 0: AMD Radeon Graphics, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 32752 MiB
  Device 1: AMD Instinct MI50/MI60, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 16368 MiB
  Device 2: AMD Instinct MI50/MI60, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 16368 MiB
  Device 3: AMD Instinct MI50/MI60, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 16368 MiB
  Device 4: AMD Instinct MI50/MI60, gfx906:sramecc+:xnack- (0x906), VMM: no, Wave Size: 64, VRAM: 16368 MiB
| model | size | params | backend | ngl | threads | fa | ts | lm | test | t/s |
|---|---|---|---|---|---|---|---|---|---|---|
| kolibri1 78B.A3.5B Q8_0 | 77.42 GiB | 78.10 B | ROCm | 999 | 16 | 1 | 2.00/1.00/1.00/1.00/1.00 | none | pp512 | 239.01 ± 8.32 |
| kolibri1 78B.A3.5B Q8_0 | 77.42 GiB | 78.10 B | ROCm | 999 | 16 | 1 | 2.00/1.00/1.00/1.00/1.00 | none | pp2048 | 260.64 ± 4.01 |
| kolibri1 78B.A3.5B Q8_0 | 77.42 GiB | 78.10 B | ROCm | 999 | 16 | 1 | 2.00/1.00/1.00/1.00/1.00 | none | tg128 | 57.76 ± 0.10 |
build: 2280f0fd1 (11886)
hermann@7600x:~/llama.cpp$
bench5
#!/bin/bash
export HSA_OVERRIDE_GFX_VERSION=9.0.6
export HSA_ENABLE_SDMA=1
export HSA_ENABLE_PEER_SDMA=1
export GGML_CUDA_DISABLE_PEER_ACCESS=0
export HIP_VISIBLE_DEVICES=0,1,2,3,4

./build/bin/llama-bench \
  -m /mnt/hf/Kolibri-1-GGUF/Q8_0/Kolibri-1-Q8_0-00001-of-00002.gguf \
  -ngl 999 \
  -mg 0 \
  -sm layer \
  -ts 2/1/1/1/1 \
  -fa on \
  -lm none \
  -p 512,2048 \
  -n 128 \
  -t 16
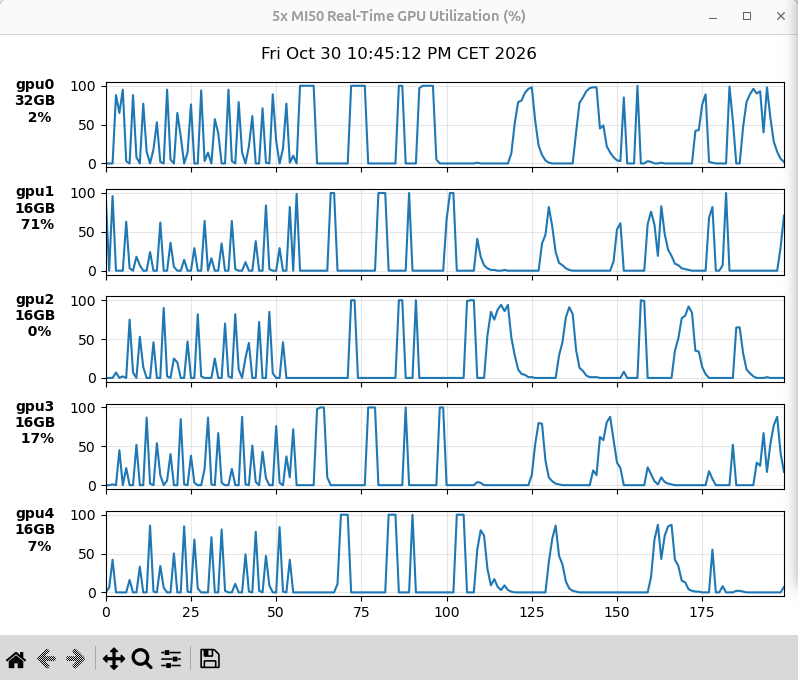
Screenshot of mi50_rt_graph.py tool (created with gemini.google.com) for real time monitoring of the 5 Instinct MI50 GPUs during above response processing: